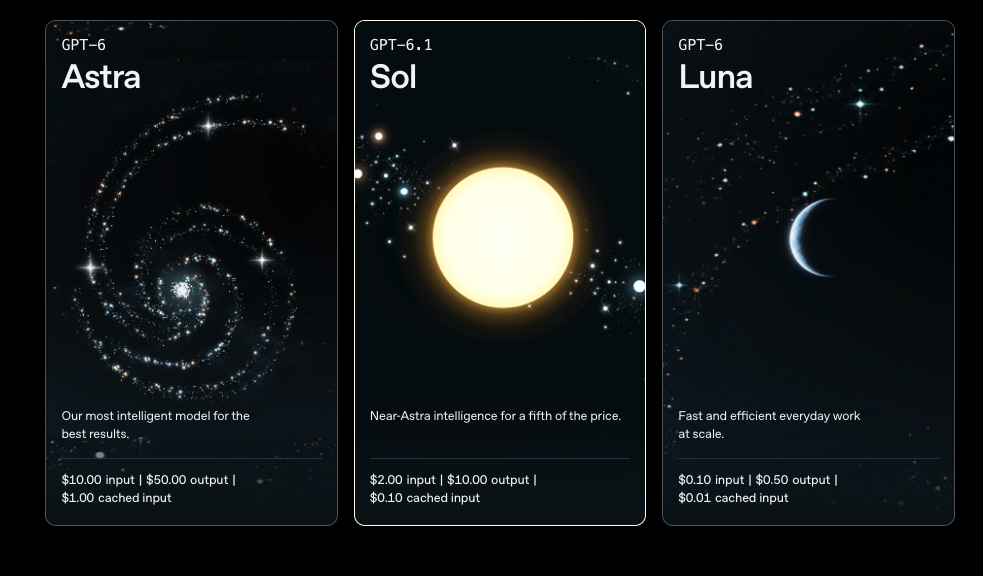
OpenAI lists cache reads at $0.10 per million tokens. This rate is of interest for recurring tasks, subject to checking their actual quality.
A reference file can be re-read with every new request sent to a model. In GPT-6.1 Sol’s pricing, OpenAI charges cached inputs at $0.10 per million tokens, against $2 for standard inputs. Output costs $10 per million. Standard input and output prices are one fifth of those of GPT-6 Astra; this ratio does not guarantee a total bill divided by five.
The launch page presents the model as an evolution of GPT-6 Sol, available in Work, Codex and the API. It reports progress on several professional-work evaluations, while specifying that tests in a research environment or via the API may differ from production use. This reservation accompanies the performance comparisons.
Keeping context worth keeping
For an editorial team or a collection direction, reuse could concern an approved corpus of references. One still has to know which version of the guidelines, catalogue or brief remains relevant. A cheaper reading of an outdated instruction creates no useful saving.
Evaluation should therefore combine two checks: the quality of the answers and the validity of the reused context. A file corrected after each error would show whether the improvement carries over to subsequent work. Human corrections, follow-ups and review time would enter into the full cost.
The cache price provides a precise purchasing parameter. The decision to entrust more work to it depends on another kind of proof: the ability to retain the right references without propagating old errors. This proof must be produced on the team’s own documents and requirements.
Cette publication est également disponible en :


